The Citation Game
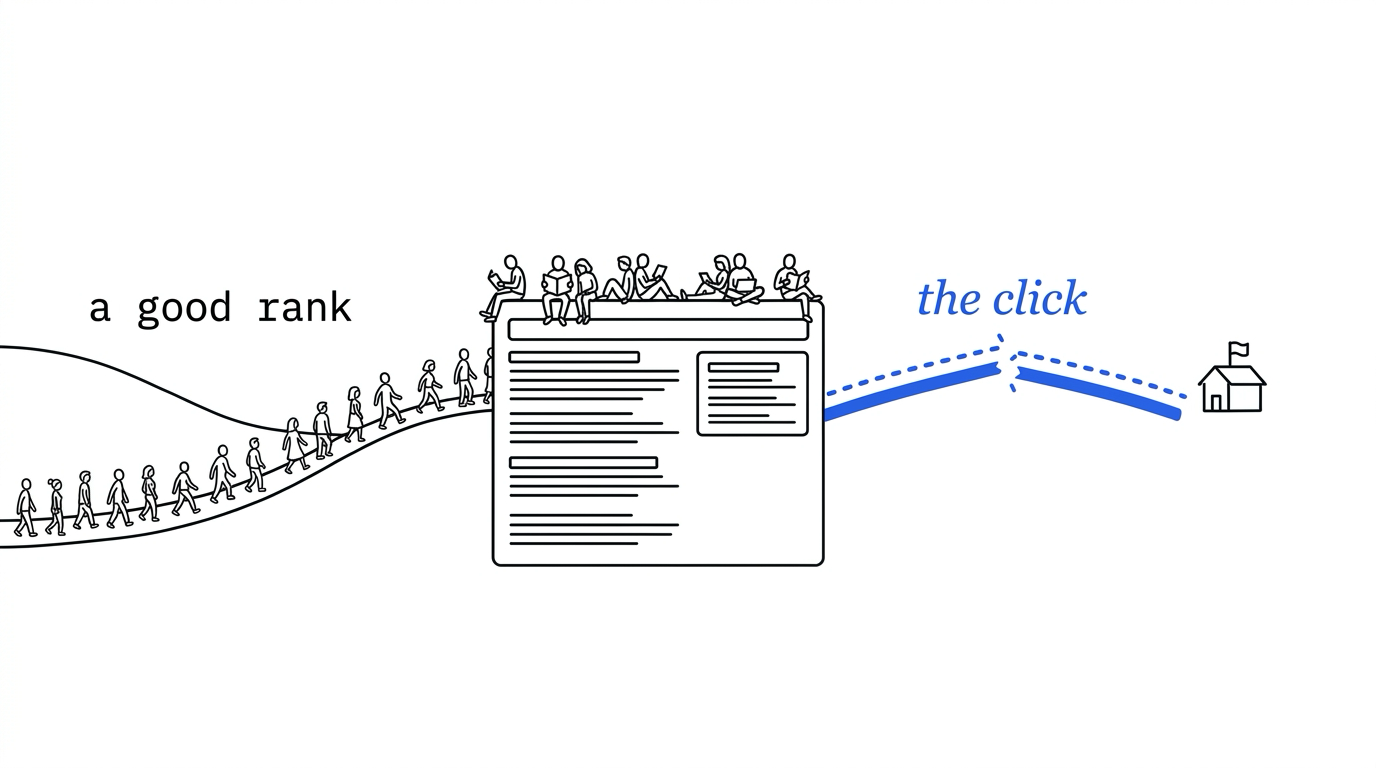
Chegg had built more than 135 million questions and answers. Its visitors kept falling.
In 2024, search engine referrals supplied 71% of Chegg Study's US traffic, according to its complaint against Google. Most of that search traffic came through Google.
Chegg's global non-subscriber traffic fell 8% year over year in the second quarter of 2024. The decline reached 19% in the third quarter and 39% in the fourth. By January 2025, traffic was down 49% from a year earlier.
The archive was still there. The route to it was failing.
I think about the teams that built their work around that route. They answered the questions people searched for, then measured the visits those answers earned. More useful pages meant more chances to be found.
That was a working model, not a failure to understand search. Chegg's dependence shows how much traffic the model could bring. It also shows how exposed a business becomes when the search page starts answering the question itself.
Chegg had built a business around answering questions. Now it said Google was using that content to keep visitors on its own page.
Those answers were reaching people who no longer needed to visit the source.
Pew studied 68,879 Google searches from the browsing records of 900 US adults in March 2025. A regular result received a click on 8% of visits with an AI summary, compared with 15% without one.
A link inside the summary received a click on just 1% of visits.
The pattern extends beyond Chegg. Seer found organic click-through rates on queries with AI Overviews fell by nearly two-thirds.
In Ahrefs' desktop data, an AI Overview was associated with a 34.5% lower click-through rate for the top result in March 2025. Its December 2025 data put the difference at 58%.
Each study measures something different; together they cannot forecast your traffic. But they make a good rank less reassuring.
The dashboard can still show where a page ranks. It cannot make the reader need another page.
Rank and sessions keep their place inside the Perception Engine, the system that decides what gets measured and rewarded. The reward can stay fixed while the behavior it was meant to track moves elsewhere.
Being named is different
Chegg tried to recover the old exchange in court. It sued Google on February 24, 2025, while announcing a review of its strategic options.
CEO Nathan Schultz said the review would not have been needed without AI Overviews. In Chegg's account, Google had taken the answers and kept the traffic.
Judge Amit Mehta dismissed the suit on September 30, 2026. On the expectation of traffic in return for free content, he wrote: "an expectation is not an agreement".
That distinction reaches beyond the courtroom. A business can plan around a flow of visitors for years without owning the conditions that send them.
The ranking game treated the visit as the return for having an answer. The answer page can now use the source without delivering that return.
Nor is this a fight for the only citation. Pew found that 88% of AI summaries cited three or more sources. Just 1% cited a single source.
The scarce thing is the click, not the mention.
I call being named inside the answer The Citation Game. Winning it means checking both where your name appears and what the answer says about you.
Semrush's survey of 1,030 US shoppers, conducted in December 2025, helps explain why. For brands that appear in AI responses, only 20% said appearing higher or earlier made a brand stand out. A clearer or more detailed explanation mattered to 43%.
Clarity Beats Position is the law I take from that difference. Once a brand is named, I would check how clearly it is described. A clear page still carries no guarantee of a citation.
You can win the ranking game and lose the citation game.
What the answers read
Then what does the answer read?
I typed the query my audience uses into Claude, ChatGPT and Gemini. I recorded what came back verbatim.
Two competitors appeared by name. The language came almost directly from their oldest comprehensive pieces, articles from three and four years ago.
My content was newer and ranked better in search. It did not appear once.
My read was that the answers drew on the archive independently of the rankings I was watching. I had no proof of how the models worked.
The age of those articles was not the useful part. Their depth and specificity gave me something to check against my own work. I had been watching the position and had not checked the answer.
I also tested three client product pages. I asked ChatGPT to recommend a solution in each category. Two pages read like ad copy.
The page with actual specs and pricing tiers won. It gave the answer concrete things to say about the product.
Three pages cannot establish a rule for every category. I now check whether a page explains the product before polishing a broad promise.
I can compare the description with the source. I cannot get that comparison from a ranking report alone. The words carried into the answer are part of the marketing now.
The visitor who follows those words arrives having already heard a description of you.
At Ahrefs, Patrick Stox reported that AI search supplied 0.5% of traffic but 12.1% of signups over a 30-day period. Those results came from one company's site; other businesses could see different rates.
Semrush's estimate puts an AI search visitor at 4.4 times the value of an organic visitor, measured by conversion rate. It publishes no sample or underlying rates for that comparison.
I would not put either figure into a revenue forecast for a client. I would check whether the people arriving from an answer behave differently.
They are not necessarily arriving convinced. In the Semrush shopper survey, 86% said they verified AI recommendations elsewhere at least sometimes. The answer can introduce you without settling the decision.
Seer also found cited brands received 35% more organic clicks than uncited brands. That does not prove the citation caused the increase.
I call that the Citation Flywheel, but I stop at what I can check: being named, then visited by people already told. Some sites see those visitors convert better.
The description matters before the visit, and the business still has to meet it afterward. That is marketing work, even when the visit never arrives.
The plan gets another cycle
But AI answers draw on pages that rank. If good SEO gets you into the source list, why change the work?
The overlap is real. Seer's cited brands also earned more clicks.
Nor does citation work promise leads inside a quarter. Building depth takes months, and attribution is hard.
Citation work cannot rescue a content farm. The team has to replace thin pages with deeper work, and that takes time.
I would keep the search work that makes pages useful. I would stop treating a ranking as proof that an answer will describe the business well.
Pranjal Aggarwal and his coauthors tested changes to source pages in the GEO paper, published at KDD in 2024. Adding cited sources, quotations or statistics improved visibility in generative answers by up to 40%.
Keyword stuffing gave little to no improvement. These were lab benchmark results; live Google performance was outside their scope. I take them as a reason to test the content itself, with no new target to promise.
I expect the teams most invested in the ranking playbook to renew it for one more cycle, with tighter targets. That is the Position Lock: keeping the plan and asking it to work harder.
I expect the response to lost traffic to be more pages before it becomes fewer, deeper ones. I think the library and the reporting make the old plan easier to renew.
If the teams with the biggest content libraries are the first to cut them back to fewer, deeper pages, I am wrong.
Check the words
What do you do on Monday?
Run the queries your customers use in Claude, ChatGPT and Gemini. Record the answers verbatim. Note who gets named and the exact words used to describe them.
Then add your brand name and run them again. Compare the description you get with the one you give customers. A mention alone will not tell you whether the answer understood what you do.
Write one sentence that names the domain you own and the angle you own it from. Koray GÜBÜR calls these the central entity and source context. His terms are useful if they force a precise answer.
Use that sentence to choose the topic that matters most. Build one deep page before adding ten thin ones. Give it named authorship, cited evidence and clear details a buyer can check.
I would start there before commissioning another content calendar. Then I would run the queries again and compare the words as well as counting the mentions.
Chegg had more than 135 million questions and answers. Its archive could not guarantee the traffic it expected. Mehta's distinction still holds: "an expectation is not an agreement".
An answer can carry your work without carrying anyone back to you.
I keep a record of who the answers name, and share what I find by email.